Chapter 7: Learning from mistakes
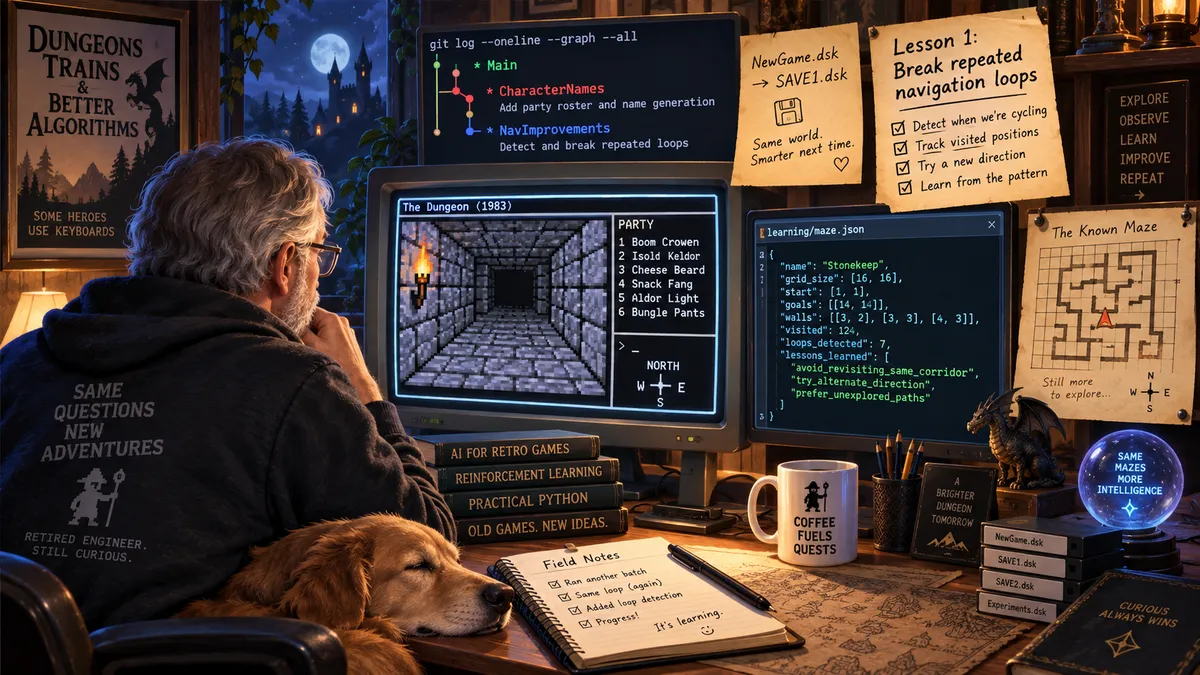 The evening begins with some cleanup work to make development easier. First, I notice that Moose is deleting the pre-made characters every time a new campaign is started. No need to do this. I took over manually and deleted these characters, saved a NewGame.dsk file, and told Moose to always use this when starting a new campaign.
Next we did work on the character names. They were too-often just silly, so I toned it down so that we now get 25% normal name, 50% either first or last name is silly, 25% completely silly name.
Now onto the feature development. I noticed on the most recent run that Moose walked to the end of a corridor and started turning left, right, left, right, till he ran out of keystrokes. Instead of telling him this, I want him to implement a learning engine that will persist through all campaigns. This is where the AI starts learning how to play.
I want you to start LEARNING about maze movement. Is there a way that you can start building up learnings and observations at the GAME level (ie these will persist throughout all future campaigns) where you learn things about navigation? I do not know how to do this, but I think you do. For example, I want you to be able to "notice how you are playing" and be able to modify your game play. If you start spinning in circles, for example, I want you to learn how not to spin in circles. I would like this learning to be scoped to navigation. Generally learning will be paired with a handler. So this will be Maze learning. Tell me your thoughts.
Moose responds with:
The learning will be transparent rather than mysterious: observations and learned rules will be stored in a readable Maze-specific file, so we can see exactly what the program has concluded and why. In short, the map remembers the dungeon; Maze learning remembers how to explore dungeons.
Make it so, Moose
It now keeps persistent learning in learning/maze.json, separate from any campaign. The Maze handler records navigation states, map-knowledge growth, blocked moves, loop events, and successful loop escapes.
As we perform the next run, I see in the logs that Moose detects the right-left-right-left, makes a note in /learning/maze.json and escapes the navigation loop. When I run again, Moose hits and escapes the loop, and updates /learning/maze.json, noting that this condition has been hit.
We are iterating rapidly on design and developing out the learning json. The learning also includes history, so that we can verify whether or not Moose is truly learning; the mistakes should decrease over time.
Keystrokes are still set to only be 100, and the combat handler isn't working well, so the game keeps crashing in the maze - but that's a problem for another night.